
Llama-Server Router Mode - Dynamic Model Switching Without Restarts
Serve and swap LLMs without restarts.
For a long time, llama.cpp had a glaring limitation:
you could only serve one model per process, and switching meant a restart.
Serve and swap LLMs without restarts.
For a long time, llama.cpp had a glaring limitation:
you could only serve one model per process, and switching meant a restart.
Serve open models fast with SGLang.
SGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency and high-throughput inference across everything from a single GPU to distributed clusters.
Hot-swap local LLMs without changing clients.
Soon you are juggling vLLM, llama.cpp, and more—each stack on its own port. Everything downstream still wants one /v1 base URL; otherwise you keep shuffling ports, profiles, and one-off scripts. llama-swap is the /v1 proxy before those stacks.
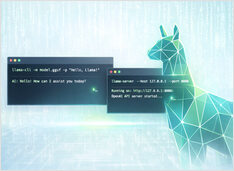
Run GGUF models with the CLI and server
llama.cpp is a C/C++ inference engine for GGUF models: llama-cli for interactive chat, llama-completion for scripted prompts, and llama-server for an OpenAI-compatible HTTP API.